

AI-powered applications often perform impressively during initial development. The real challenge begins when those systems move into production environments where speed, reliability, consistency, and operational costs become critical.
At Blue Trail Software, we recently faced this challenge while working on an AI-driven recruitment platform designed to evaluate candidate-job compatibility. The platform initially delivered promising results, but as usage increased, inconsistencies and performance limitations began affecting both user experience and operational efficiency.
The issue was not a complete system failure. Instead, it was a gradual breakdown caused by variability, latency, and growing costs.
This project became a lesson in an increasingly important principle for modern AI systems: Prompt engineering alone is not enough. Sustainable AI performance requires software architecture, orchestration, and deterministic design.
The Limits of Monolithic Prompt Engineering
Our platform used Large Language Models (LLMs) to evaluate candidate profiles against job descriptions and generate compatibility scores.
Initially, the implementation relied heavily on a large, instruction-rich prompt designed to manage the entire evaluation process.
This approach created several critical issues.
Inconsistent AI Scoring and Output Variability
The most significant problem was inconsistency.
The exact same candidate-job combination could produce dramatically different results:
First evaluation: 60
Second evaluation: 10
Third evaluation: 95
No underlying data changed between evaluations.
The system was producing unpredictable outputs, which severely impacted trust and usability.
For recruitment workflows, this level of variability creates major concerns:
Reduced confidence in recommendations
Poor user experience
Difficulty explaining results
Increased operational risk
Consistency is essential for production AI systems.
Latency and Performance Bottlenecks
The original architecture required the model to process:
Hundreds of instructions
Entire profile files
Large contextual datasets
Complex scoring logic
This created significant delays. Average evaluation time: 18 seconds per request
For real-world users, this created friction and negatively affected platform responsiveness.
High Token Consumption and Operational Costs
Large prompts and unrestricted text outputs generated unnecessary token usage.
The result:
Increased API expenses
Inefficient scaling
Reduced profitability
As AI systems grow, token efficiency becomes a business concern as much as a technical one.
Re-Engineering the Architecture: From Prompt to AI Orchestration
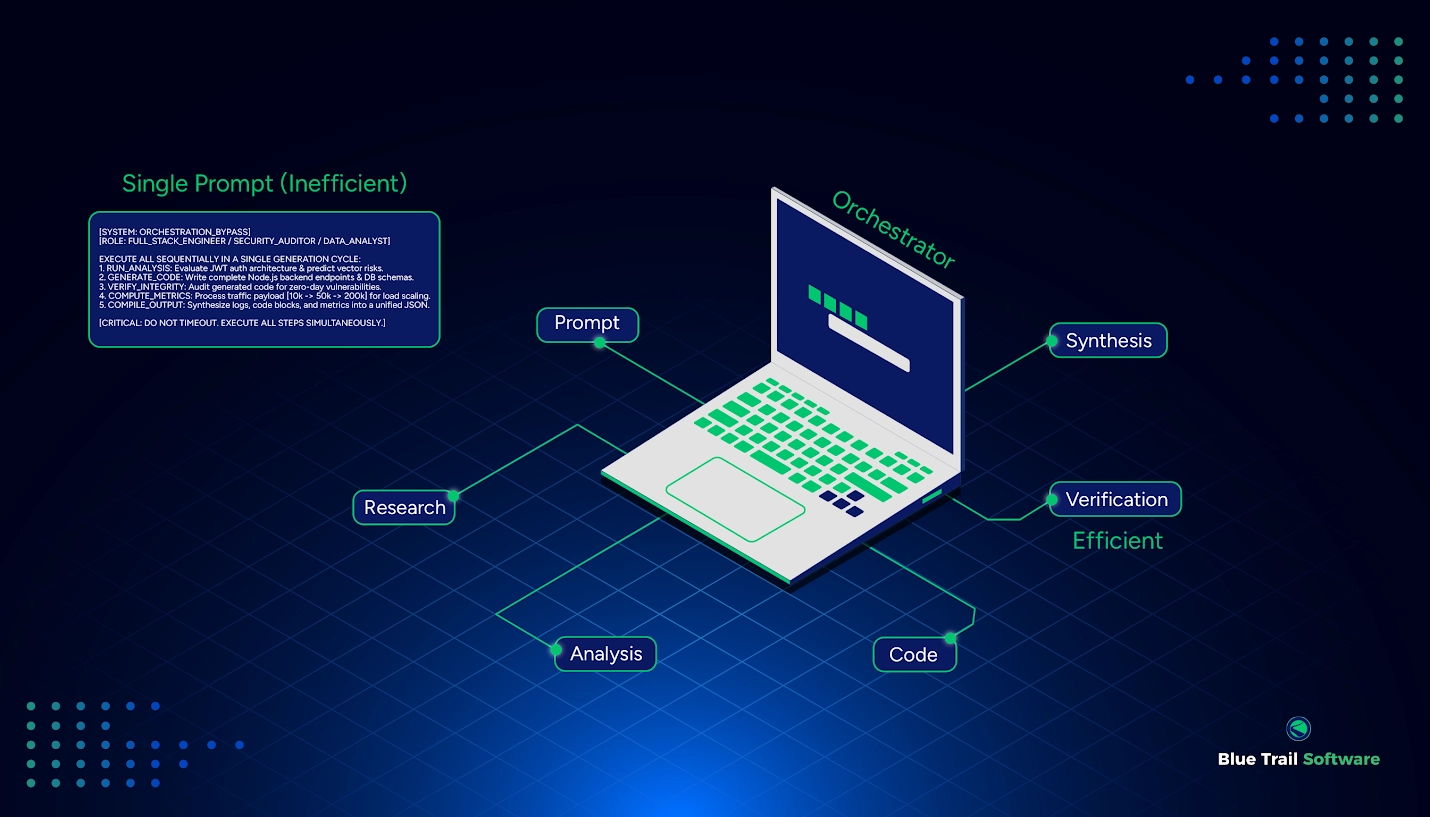
Rather than continuing to optimize a single massive prompt, we redesigned the system architecture entirely.
The new approach introduced a sub-agent orchestration model.
Instead of asking one AI model to perform everything, we distributed responsibilities across specialized components.
Step 1: Introducing an Orchestrator Agent
A central orchestration layer was created to manage the evaluation process.
The orchestrator:
Receives candidate and job information
Retrieves contextual information through ChromaDB
Extracts key evaluation categories
Routes information to specialized components
Key categories included:
Work experience
Technical skills
Education
Industry alignment
Required competencies
This transformed a single AI task into smaller focused evaluations.
Parallel AI Processing for Faster Performance
Each category was sent to specialized sub-agents simultaneously.
Rather than sequential processing:
Old process
Candidate → Single prompt → Evaluation
New process
Candidate → Orchestrator → Multiple specialized agents → Aggregated results
Parallel execution reduced processing time significantly.
Results:
Previous latency: 18 seconds
New latency: 8 seconds
This represented more than a 50% reduction in waiting time.
Moving Business Logic Out of the LLM
Another major improvement involved separating AI reasoning from deterministic application logic.
Instead of allowing the LLM to perform calculations and return open-ended responses:
JSON output became mandatory
Mathematical operations moved into the application API
Rating calculations became deterministic

This produced several advantages:
Reduced hallucinations
The LLM no longer generated inconsistent calculations.
Lower token consumption
Structured outputs required fewer tokens.
Greater transparency
Administrators could now view:
Individual category scores
Detailed evaluation criteria
Final weighting logic
The system became explainable rather than opaque.
Improving AI Consistency Through Data Preprocessing
During iterative testing with tools like Claude Code, we discovered an important insight: The issue was not primarily flawed rules. The issue was incomplete contextual understanding.
When information lacked clarity, the model improvised. That improvisation caused major scoring variability.
NLP Preprocessing with Python
Before data reached the LLM, we introduced traditional Natural Language Processing techniques.
The preprocessing layer applied:
Lemmatization
Stemming
Skill normalization
Examples:
"Engineer"
"Engineering"
"Software Engineer"
These terms became semantically aligned before evaluation.
Benefits included:
Improved skill matching
Reduced ambiguity
More consistent scoring
Traditional NLP significantly strengthened AI performance.
Introducing Deterministic Decision Structures
Prompt structures were redesigned using more explicit logic.
New patterns included:
Numbered rules
Decision tables
Stop conditions
If-else style evaluation paths
Example: If a mandatory requirement is missing: Return result → Stop evaluation
This reduced unnecessary model interpretation and increased predictability.
Prioritizing Critical Skills and Requirements
Not every job requirement should contribute equally to candidate evaluation.
We introduced weighted critical keywords to ensure essential qualifications received stronger influence.
Examples: Critical requirements:
Required programming languages
Certifications
Years of experience
Mandatory domain expertise
This produced more realistic ranking behavior and improved recommendation quality.
Reducing AI Costs with Database Caching
One of the most impactful optimizations involved introducing a caching layer.
Each candidate-job pair generated a unique hash.
The system checks: Has this evaluation already been performed?
If no underlying data changes:
No LLM request executes
Cached results are returned instantly
Effectively: Recurring evaluations became: $0 cost
Benefits included:
Lower API expenses
Faster response times
Reduced infrastructure load
Results: Performance, Stability, and Cost Improvements
The architectural redesign generated measurable improvements across multiple dimensions.
Token Consumption
Previous: 5,000 tokens
Current: 3,500 tokens
Improvement:
25% reduction
AI Output Stability
Previous average score variance: 37 points
Current average score variance: 5 points
Improvement:
Approximately 86% greater consistency
API Cost Reduction
Combined improvements from:
Token optimization
Structured responses
Database caching
Result: 30% reduction in overall API costs

Lessons Learned: Prompt Engineering Alone Is Not Enough
One of the most important lessons from this project is that prompt engineering is not a final destination.
Production AI systems require a broader engineering approach involving:
Orchestration
Deterministic logic
NLP preprocessing
Structured outputs
Caching strategies
Continuous optimization
The most successful AI systems are not necessarily the ones with the most sophisticated prompts. They are the systems supported by strong software architecture.
Final Thoughts
AI systems increasingly require the same principles as any mature software platform:
Scalability
Reliability
Predictability
Observability
Cost efficiency
Through this redesign we achieved:
25% lower token usage
30% lower operational costs
More than 50% faster evaluations
Dramatically improved consistency
But the most valuable outcome was trust.
Users no longer depend on the randomness of a prompt. They depend on a reliable system designed for production.
The future of AI applications may not be defined by better prompts alone. It will increasingly be defined by better engineering.

