Painless Local Kubernetes: Complete Beginner’s Guide to Kind
Juan Sebastian Scatularo||Read 10 min
In the era of AI, let’s pivot for a moment to platform engineering.
Developing and testing cloud-oriented applications is often a heavy burden. Spinning up test environments in real cloud providers such as AWS can become expensive, slow, and difficult to isolate in continuous integration workflows.
For engineering teams, this creates a practical challenge: how do you get a realistic environment for developing and testing cloud-native applications without introducing unnecessary infrastructure cost, setup time, or complexity?
So in this post, we’ll explore an essential tool for learning Kubernetes and then take it a step further by using Kubernetes as the core runtime to build our own AWS clone, inspired by LocalStack and Floci.
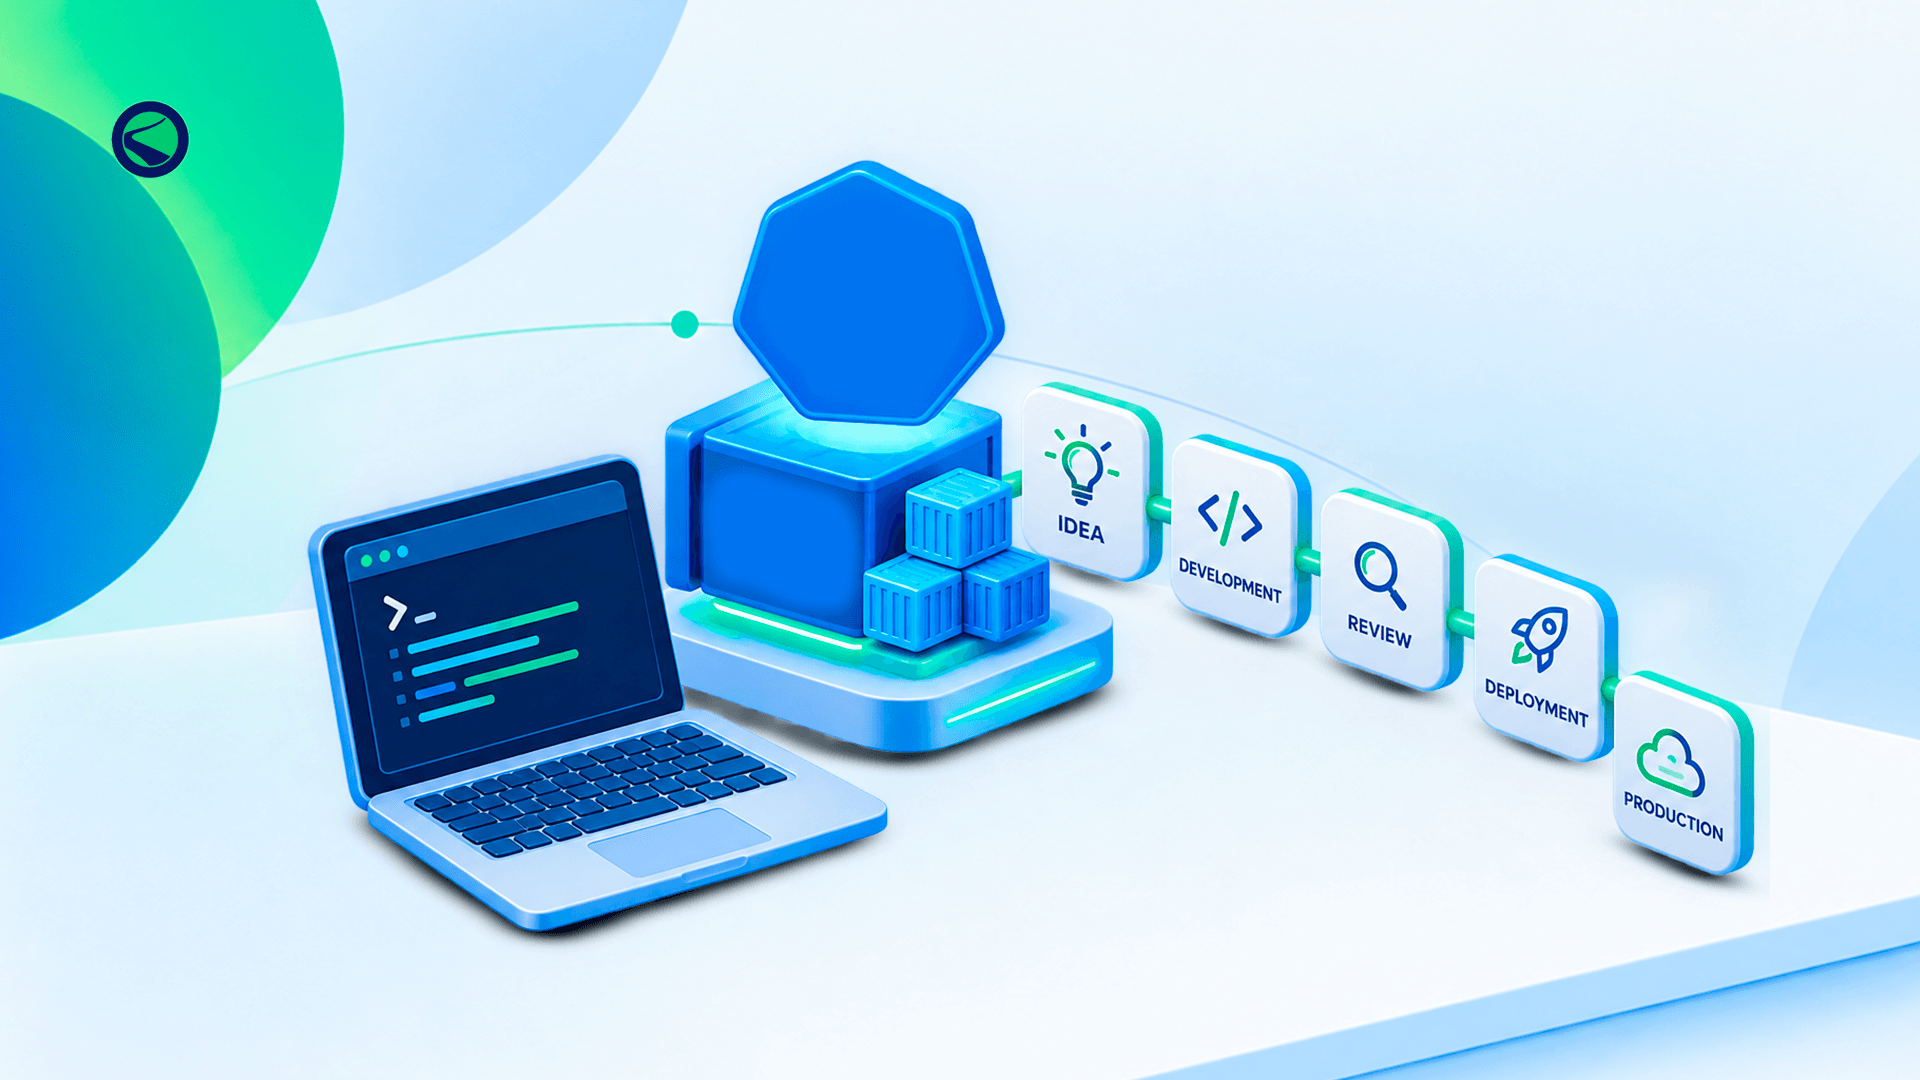
This is Kind (Kubernetes IN Docker). It is an official Kubernetes project tool that allows you to spin up a complete cluster by running each node as a Docker container.
In this series of articles we will explore Kind not just as an essential tool to learn Kubernetes, but as the core runtime to build an ambitious project: our own lightweight, declarative AWS emulator inspired by LocalStack/Floci.
For technology leaders, there is a broader engineering lesson here. Local infrastructure tools such as Kind are not simply developer conveniences. They can help engineering organizations create more reproducible environments, shorten infrastructure feedback loops, and experiment with cloud-native architectures before committing resources to shared or production infrastructure.
At Blue Trail Software, this type of engineering problem sits at the intersection of software development, cloud-native engineering, DevOps, QA, automation, and infrastructure. The ability to work across those layers matters because modern software delivery increasingly depends on how effectively application teams interact with infrastructure.
1. What is Kind and Why Choose it?
Kind is a tool that allows you to spin up a Kubernetes cluster easily in minutes with almost no overhead. It was originally designed to test Kubernetes code itself but could be used to do more things than that.
There exist various options to start up a local Kubernetes cluster but Kind is a lightweight, certified and quick option that just works on multiple configurations.
Kind: Runs nodes natively as Docker containers. It boots up in less than a minute, uses very few resources, and is extremely easy to use in CI pipelines.
Minikube: The classic standby. Although it includes a Docker driver, it usually spins up a full virtual machine by default, leading to higher CPU and memory consumption as well as longer boot times and will introduce some unnecessary overhead to our ultimate goal.
Docker Desktop: Offers a single-node cluster that can be enabled right from its interface. It is very convenient if you already have it installed, but lacks native support for complex multi-node topologies, for instance.
If you are looking for a lightweight environment that simulates real production scenarios without slowing down your development machine or CI server, Kind is the clear winner and our choice.
Why does this choice matter to engineering teams?
The choice of a local Kubernetes tool is ultimately an engineering tradeoff.
A development environment needs to be realistic enough to validate how an application behaves, but lightweight enough that developers and CI systems can use it without excessive infrastructure overhead.
Kind addresses that tradeoff by running Kubernetes nodes as containers. That makes it particularly useful when engineers need to reproduce Kubernetes environments locally, experiment with multi-node configurations, or integrate Kubernetes-based testing into automated workflows.
For technology leaders, this translates into a broader consideration: engineering productivity is affected not only by the application stack, but also by the environments engineers have to work with every day.
2. Prerequisites and Installation
To get started with Kind, you need to have three essential tools installed and configured.
Docker: the engine that will run the containers acting as your nodes
kubectl: The command-line tool to interact with your Kubernetes cluster
kind: The binary that will orchestrate the creation of your local clusters
freelens or k9s: Kubernetes CLI to manage your clusters in Style (optional)
Installation on Linux
The most convenient and recommended method for any environment is to directly download the official Kind binary and move it to your local execution path.
To spin up a basic cluster with a single node that functions as both control plane and worker, simply run:
kind create cluster --name my-cluster
Kind will handle downloading the necessary image (which contains the entire Kubernetes ecosystem), preparing certificates, initializing the control plane, and configuring your local ~/.kube/config file so that kubectl automatically points to this new cluster.
This simple workflow illustrates one of Kind’s biggest advantages: engineers can create a disposable Kubernetes environment without manually provisioning a complete cloud infrastructure stack.
Advanced Creation: Multi-Node Configuration
One of Kind’s greatest strengths is how easy it makes simulating realistic production topologies on your local machine.
By creating a YAML configuration file, we can define exactly how many control plane and worker nodes we want in our lab.
Create a file named config.yaml:
kind: Cluster
apiVersion: kind.x-k8s.io/v1alpha4
nodes:
- role: control-plane
- role: worker
- role: worker
This manifest tells Kind that we want to deploy a cluster composed of three containers: one control plane and two independent worker nodes.
Now let’s initialize the cluster by using this specific configuration:
Once the start up is completed we can verify that the cluster was spun up correctly using inspection commands:
# List clusters managed by Kind
kind get clusters
# List nodes detected by Kind
kind get nodes
# Verify node status at the Kubernetes level with kubectl
kubectl get nodes
Why does a multi-node local cluster matter?
This is where a local Kubernetes environment becomes more than a learning tool.
A multi-node cluster allows engineers to experiment with infrastructure topologies that are closer to real distributed environments. Instead of discovering configuration or deployment problems after an application reaches a shared environment, teams can investigate those behaviors earlier in the development cycle.
For engineering leaders, this is important because early technical validation reduces the amount of infrastructure-dependent troubleshooting that has to happen later in the delivery process.
It also demonstrates an important engineering capability: understanding how application behavior, deployment configuration, orchestration, and infrastructure interact.
4. The Step Everyone Forgets: Loading local container images
You build your local application, compile its Docker image with:
docker build -t my-app:1.0
You write a Kubernetes manifest referencing that image tag, apply it, and your Pods get permanently stuck in a loop with the ErrImagePull or ImagePullBackOff error.
Why does this happen?
Kind’s cluster runs inside its own isolated containers and does not automatically have visibility into the Docker engine running on your host machine.
When trying to spin up the Pod, Kubernetes attempts to find and download your my-app:1.0 image from public registries on the Internet, such as Docker Hub.
The solution:
Kind comes with a dedicated utility that takes the image from your host’s local Docker and injects it directly into the internal Docker engine running inside the cluster nodes.
Run this command whenever you compile a new local version of your image. Only then will Kubernetes be able to deploy the Pod successfully without trying to pull it from the Internet.
Why is this small detail important?
This is exactly the type of infrastructure interaction that can create friction in a development workflow.
The problem isn't the application itself. The problem is that the application, container runtime, and Kubernetes environment do not automatically share the same view of the image.
Understanding these boundaries is part of effective cloud-native engineering.
For teams building and testing modern applications, these seemingly small environment issues can accumulate into significant development friction. This is why reproducible environments and well-designed developer workflows are platform-engineering concerns, not just tooling preferences.
5. Practical Walkthrough: Deploying your first app
Create a file named app-deployment.yaml to define a deployment. This is the way you tell Kubernetes what your desired state is.
Next, define a file named app-service.yaml to expose this replica internally via a ClusterIP service.
apiVersion: v1
kind: Service
metadata:
name: nginx-service
namespace: default
spec:
type: ClusterIP
ports:
- name: http
port: 80
targetPort: 80
selector:
app: nginx-web
Applying the Configuration
To apply the manifests to your Kind cluster you must execute:
kubectl apply -f app-deployment.yaml
kubectl apply -f app-service.yaml
To get the status and verify that both your Pod and Service are active and healthy:
kubectl get pods
kubectl get svc
Direct Access via Port-Forward
Since we defined our service as ClusterIP (accessible only within the Kubernetes cluster network), we can create a fast, temporary tunnel from our host machine using kubectl’s native port-forwarding feature:
It would be expected to see the classic Nginx welcome screen serving natively from inside your local Kind cluster.
What did we actually demonstrate?
Although this example is intentionally simple, the workflow represents a fundamental cloud-native development pattern:
Define → Deploy → Inspect → Access → Validate.
The application is described declaratively through Kubernetes manifests, deployed into a local cluster, inspected through Kubernetes commands, and validated from the developer's machine.
That same mindset becomes increasingly important as applications grow more distributed and infrastructure becomes more automated.
For engineering organizations, the value is not simply being able to run Nginx locally. The value is having an environment where engineers can experiment with Kubernetes concepts, validate deployment behavior, and develop infrastructure-aware applications without requiring a dedicated cloud environment for every iteration.
Why This Matters to Engineering Leaders
Kind is a developer tool, but the engineering problems it exposes are relevant to technology leadership.
When engineers have to wait for shared environments, manually reproduce infrastructure, or troubleshoot environment differences, the development feedback loop becomes longer.
Lightweight local Kubernetes environments can give teams another option for experimentation and early validation.
Kind configurations are defined declaratively. A cluster topology can be represented in configuration rather than manually recreated.
That approach aligns with a broader platform-engineering principle: make infrastructure behavior repeatable and easier for development teams to consume.
3. Local environments can support earlier validation
Multi-node clusters allow engineers to reproduce more realistic deployment scenarios locally.
This does not replace production infrastructure or production testing. Instead, it provides another validation layer before changes move into shared environments.
4. Infrastructure knowledge is increasingly part of software engineering
Modern engineers often need to understand more than application code.
Containers, Kubernetes, CI/CD, networking, deployment configuration, observability, security, and infrastructure automation increasingly influence how software is designed and delivered.
That is why cloud-native engineering is not simply an infrastructure discipline. It is becoming part of the broader software engineering lifecycle.
What does this demonstrate about an engineering partner?
For technology leaders evaluating a software engineering partner, the important question isn't whether a team can execute a Kubernetes command.
The more important question is whether the team understands why the infrastructure exists, how it affects application development, where automation can remove friction, and how engineering decisions affect delivery.
At Blue Trail Software, this cross-layer perspective is part of how we approach software engineering. Our capabilities span custom software development, DevOps and DevSecOps, QA, cloud-native engineering, automation, AI, and IoT.
That matters because modern engineering problems rarely stop at the application boundary.
A team may be building an AI platform, a connected device, a SaaS product, or a distributed application, but the engineering challenge often involves the same underlying questions:
How should the system be architected?
How can environments be reproduced reliably?
How can changes be validated earlier?
How can development and infrastructure workflows be automated?
How can teams move faster without sacrificing quality and security?
Kind is a small but practical example of this broader engineering mindset.
Kind and the Bigger Platform Engineering Picture
The next step in this series takes the idea considerably further.
Now that you have mastered creating and managing local Kubernetes clusters with Kind, we are ready to take a giant leap toward platform engineering and native controller development.
In the next post of the series, we will stop being mere users of Kubernetes and become infrastructure builders.
We will design the architecture for our own AWS Clone inspired by LocalStack and Floci.
We will build a lightweight API and an AWS CLI-compatible proxy that will intercept AWS CLI commands and translate them into native, declarative Pods right inside our new Kind playground.
This is where the original goal becomes particularly interesting.
We are not using Kubernetes only to deploy an application.
We are exploring how Kubernetes itself can become the runtime foundation for building infrastructure abstractions.
That is a core platform-engineering idea: instead of every development team having to understand and manage every infrastructure detail independently, engineering teams can build reusable platforms, abstractions, and workflows that make infrastructure capabilities easier to consume.
6. Quick Teardown and Cleanup
When you finish your development session and want to reclaim memory and CPU resources on your local machine, there is no need to leave background services running. Kind cleans up after itself seamlessly in seconds.
kind delete cluster --name dev-cluster
This command completely stops and removes the Docker containers acting as nodes and all the inner pods, returning your host machine to its original state without leaving a trace.
That disposable nature is another reason local Kubernetes environments are useful for experimentation: engineers can create an environment, test an idea, inspect the result, and remove the environment when finished.
Final Takeaway
Kind is a lightweight way to run Kubernetes clusters locally using Docker containers. It gives engineers a practical environment for learning Kubernetes, testing cloud-native applications, experimenting with multi-node architectures, and integrating Kubernetes into development and CI workflows.
But the larger lesson goes beyond Kind.
As software systems become more distributed and infrastructure becomes increasingly programmable, engineering teams need to understand the relationship between application code, containers, orchestration, automation, testing, and infrastructure.
For technology leaders, that cross-layer engineering capability can directly influence development velocity, environment consistency, infrastructure efficiency, and the ability to validate architectural decisions earlier.
And that is ultimately why tools such as Kind matter. They aren't just ways to run Kubernetes on a laptop.
They are practical building blocks for a more reproducible, automated, and developer-friendly approach to cloud-native engineering.
At Blue Trail Software, we apply that engineering mindset across software development, DevOps/DevSecOps, QA, cloud-native systems, automation, and emerging technologies—helping teams turn complex technical requirements into software that can be built, tested, and evolved with confidence.